Oracle SQL & Neo4j Pipeline: From Raw Kaggle Data to Optimized Queries
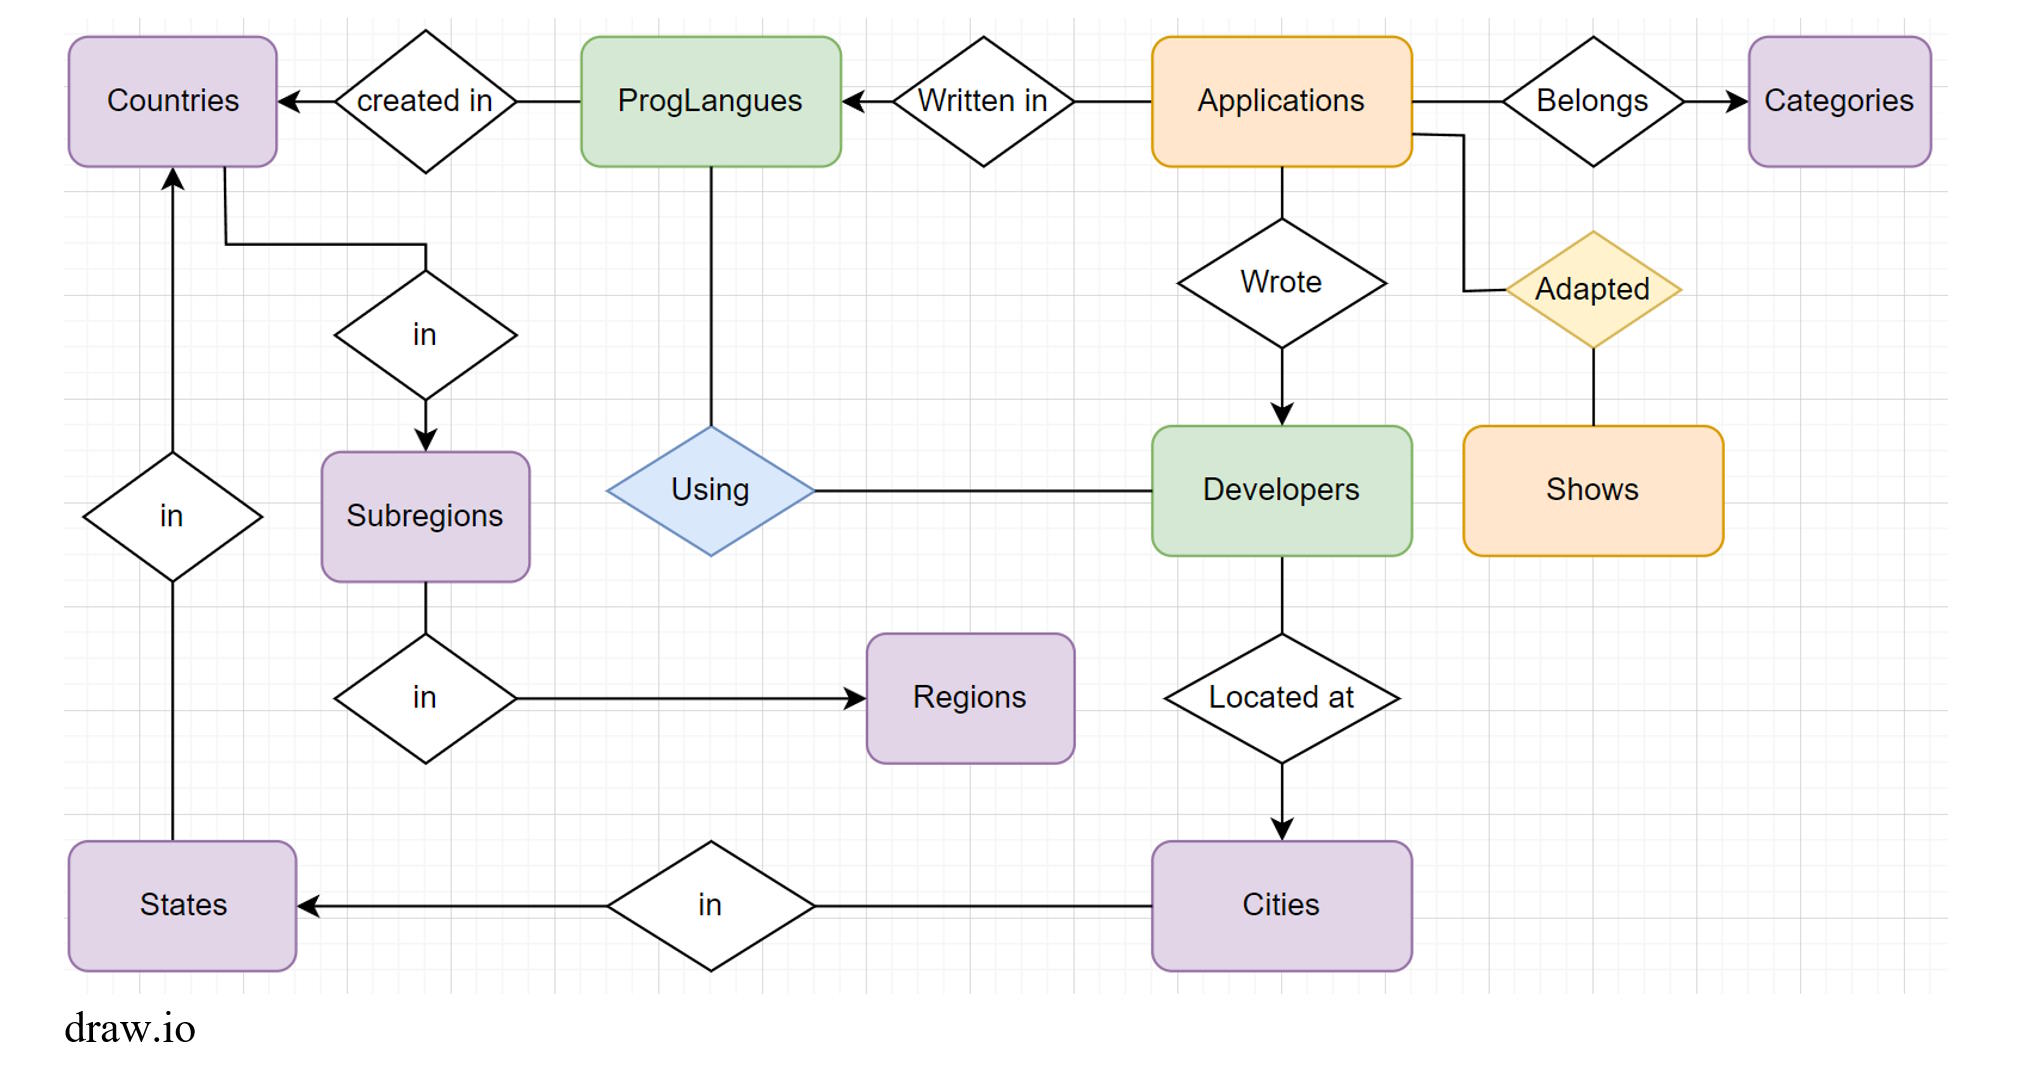
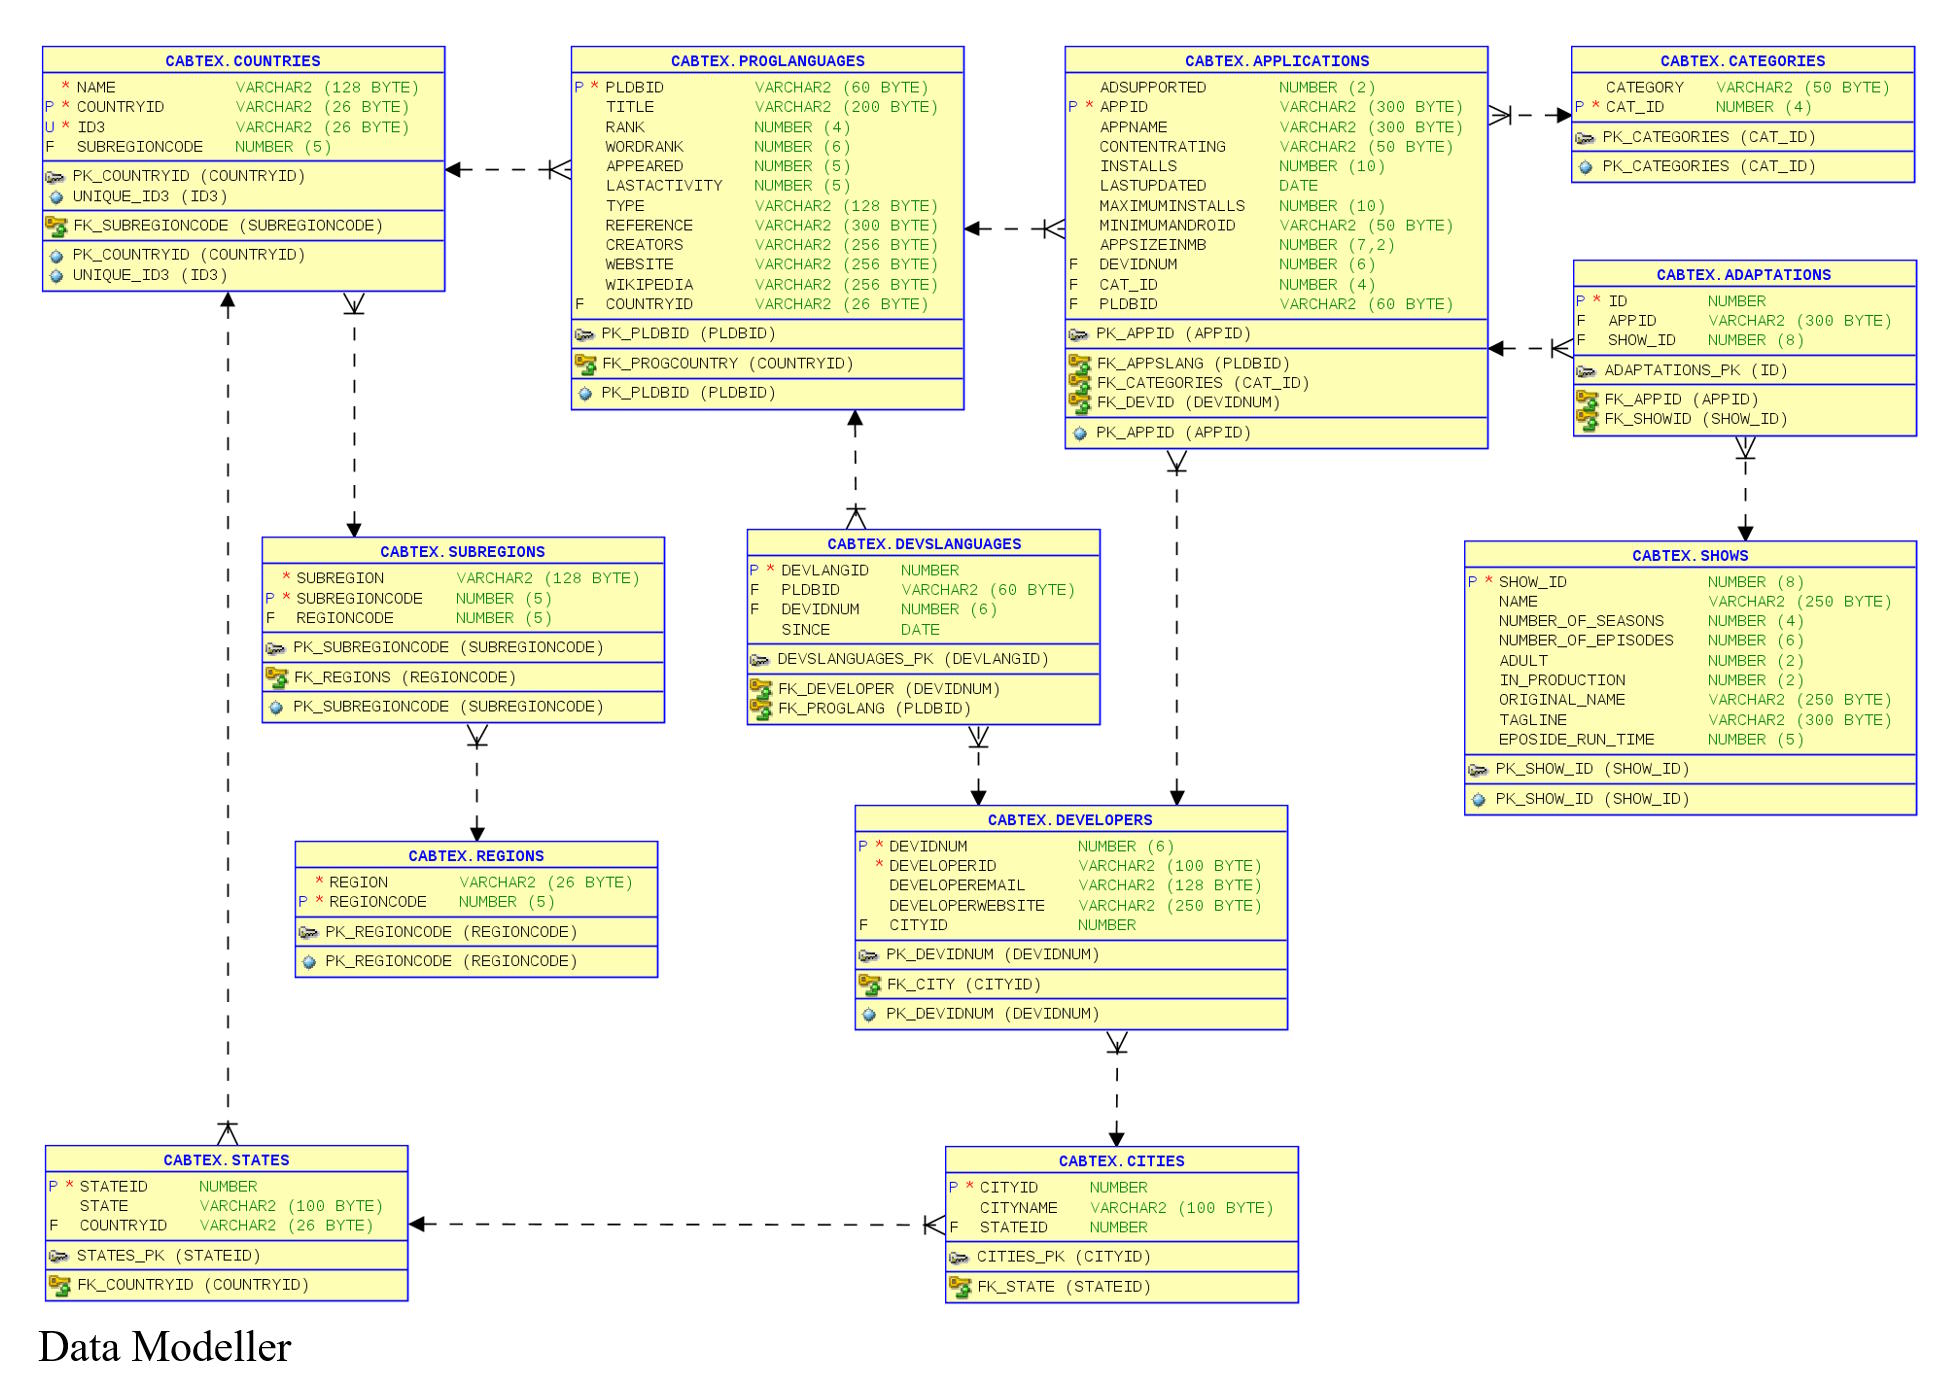
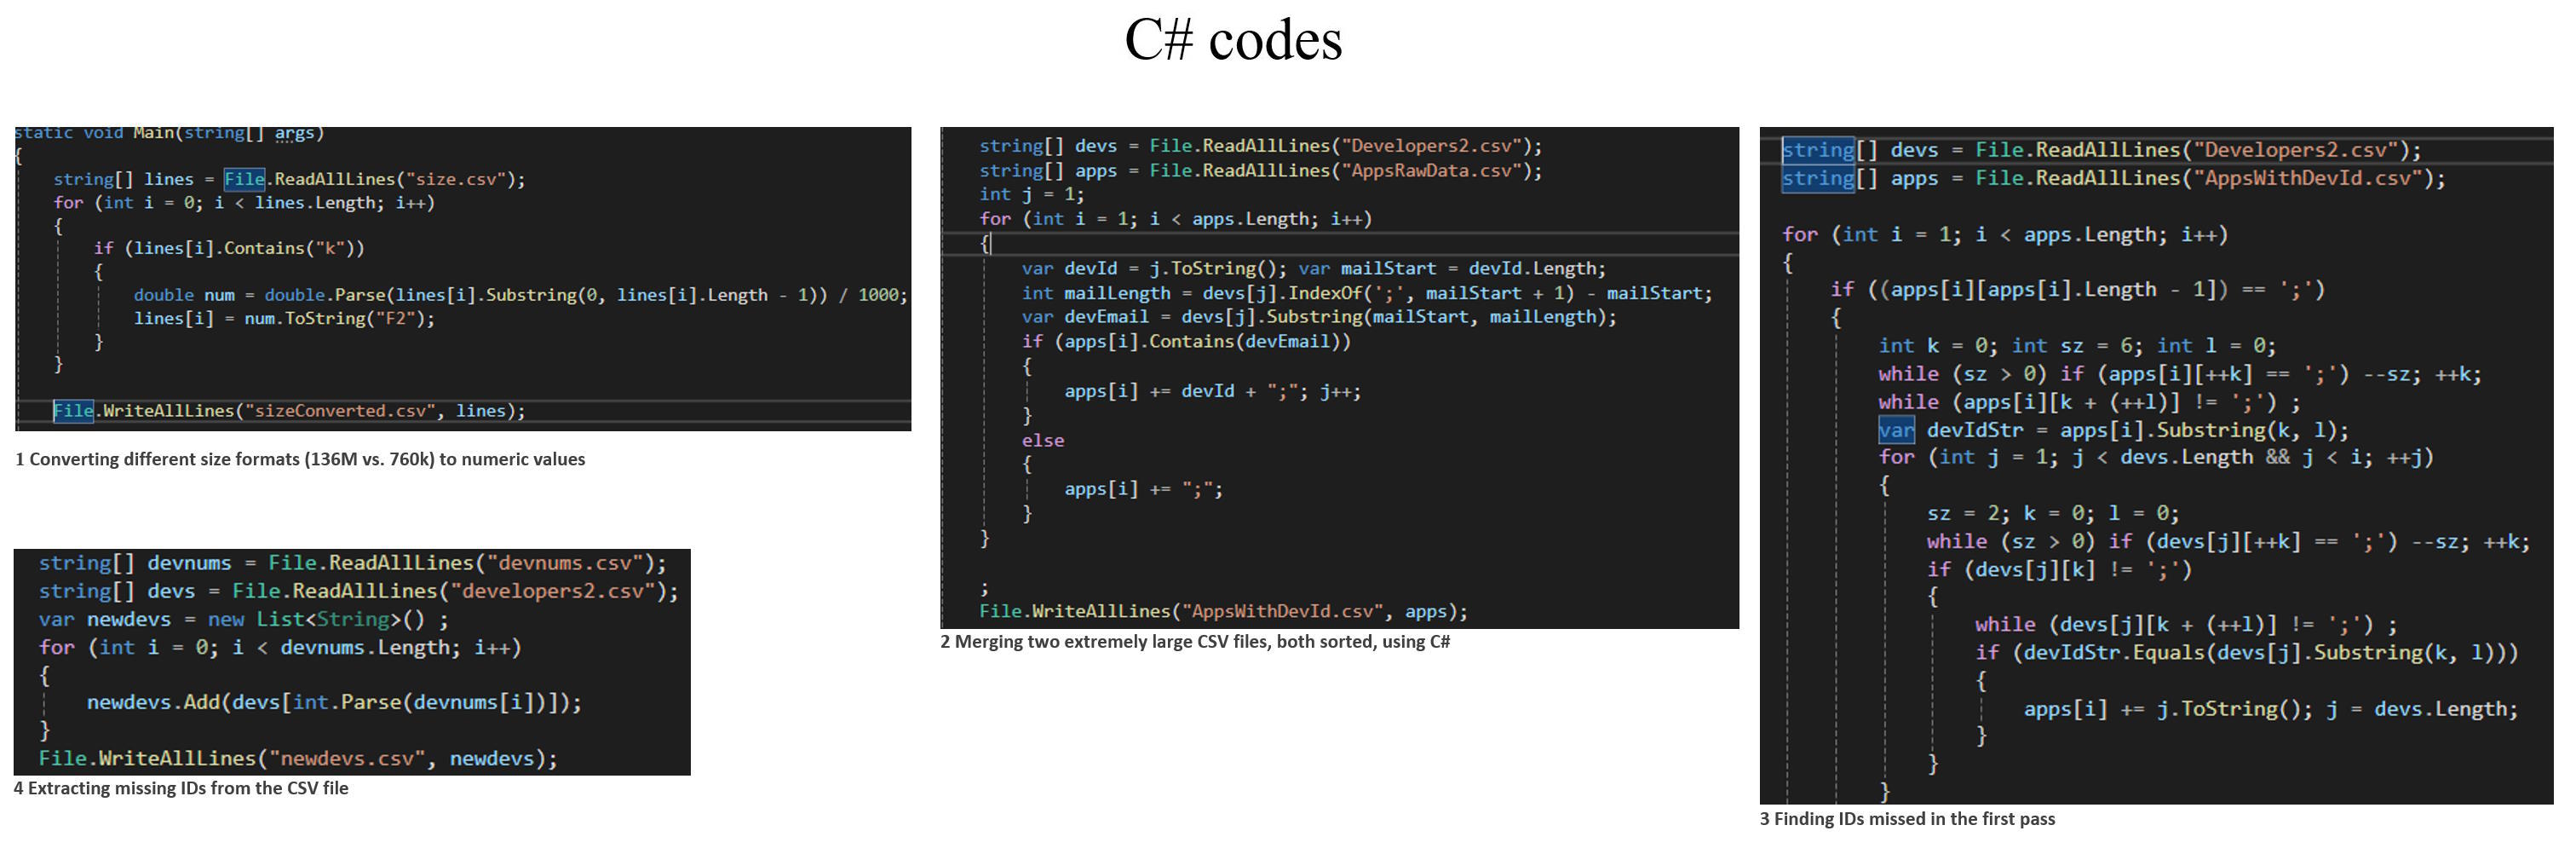
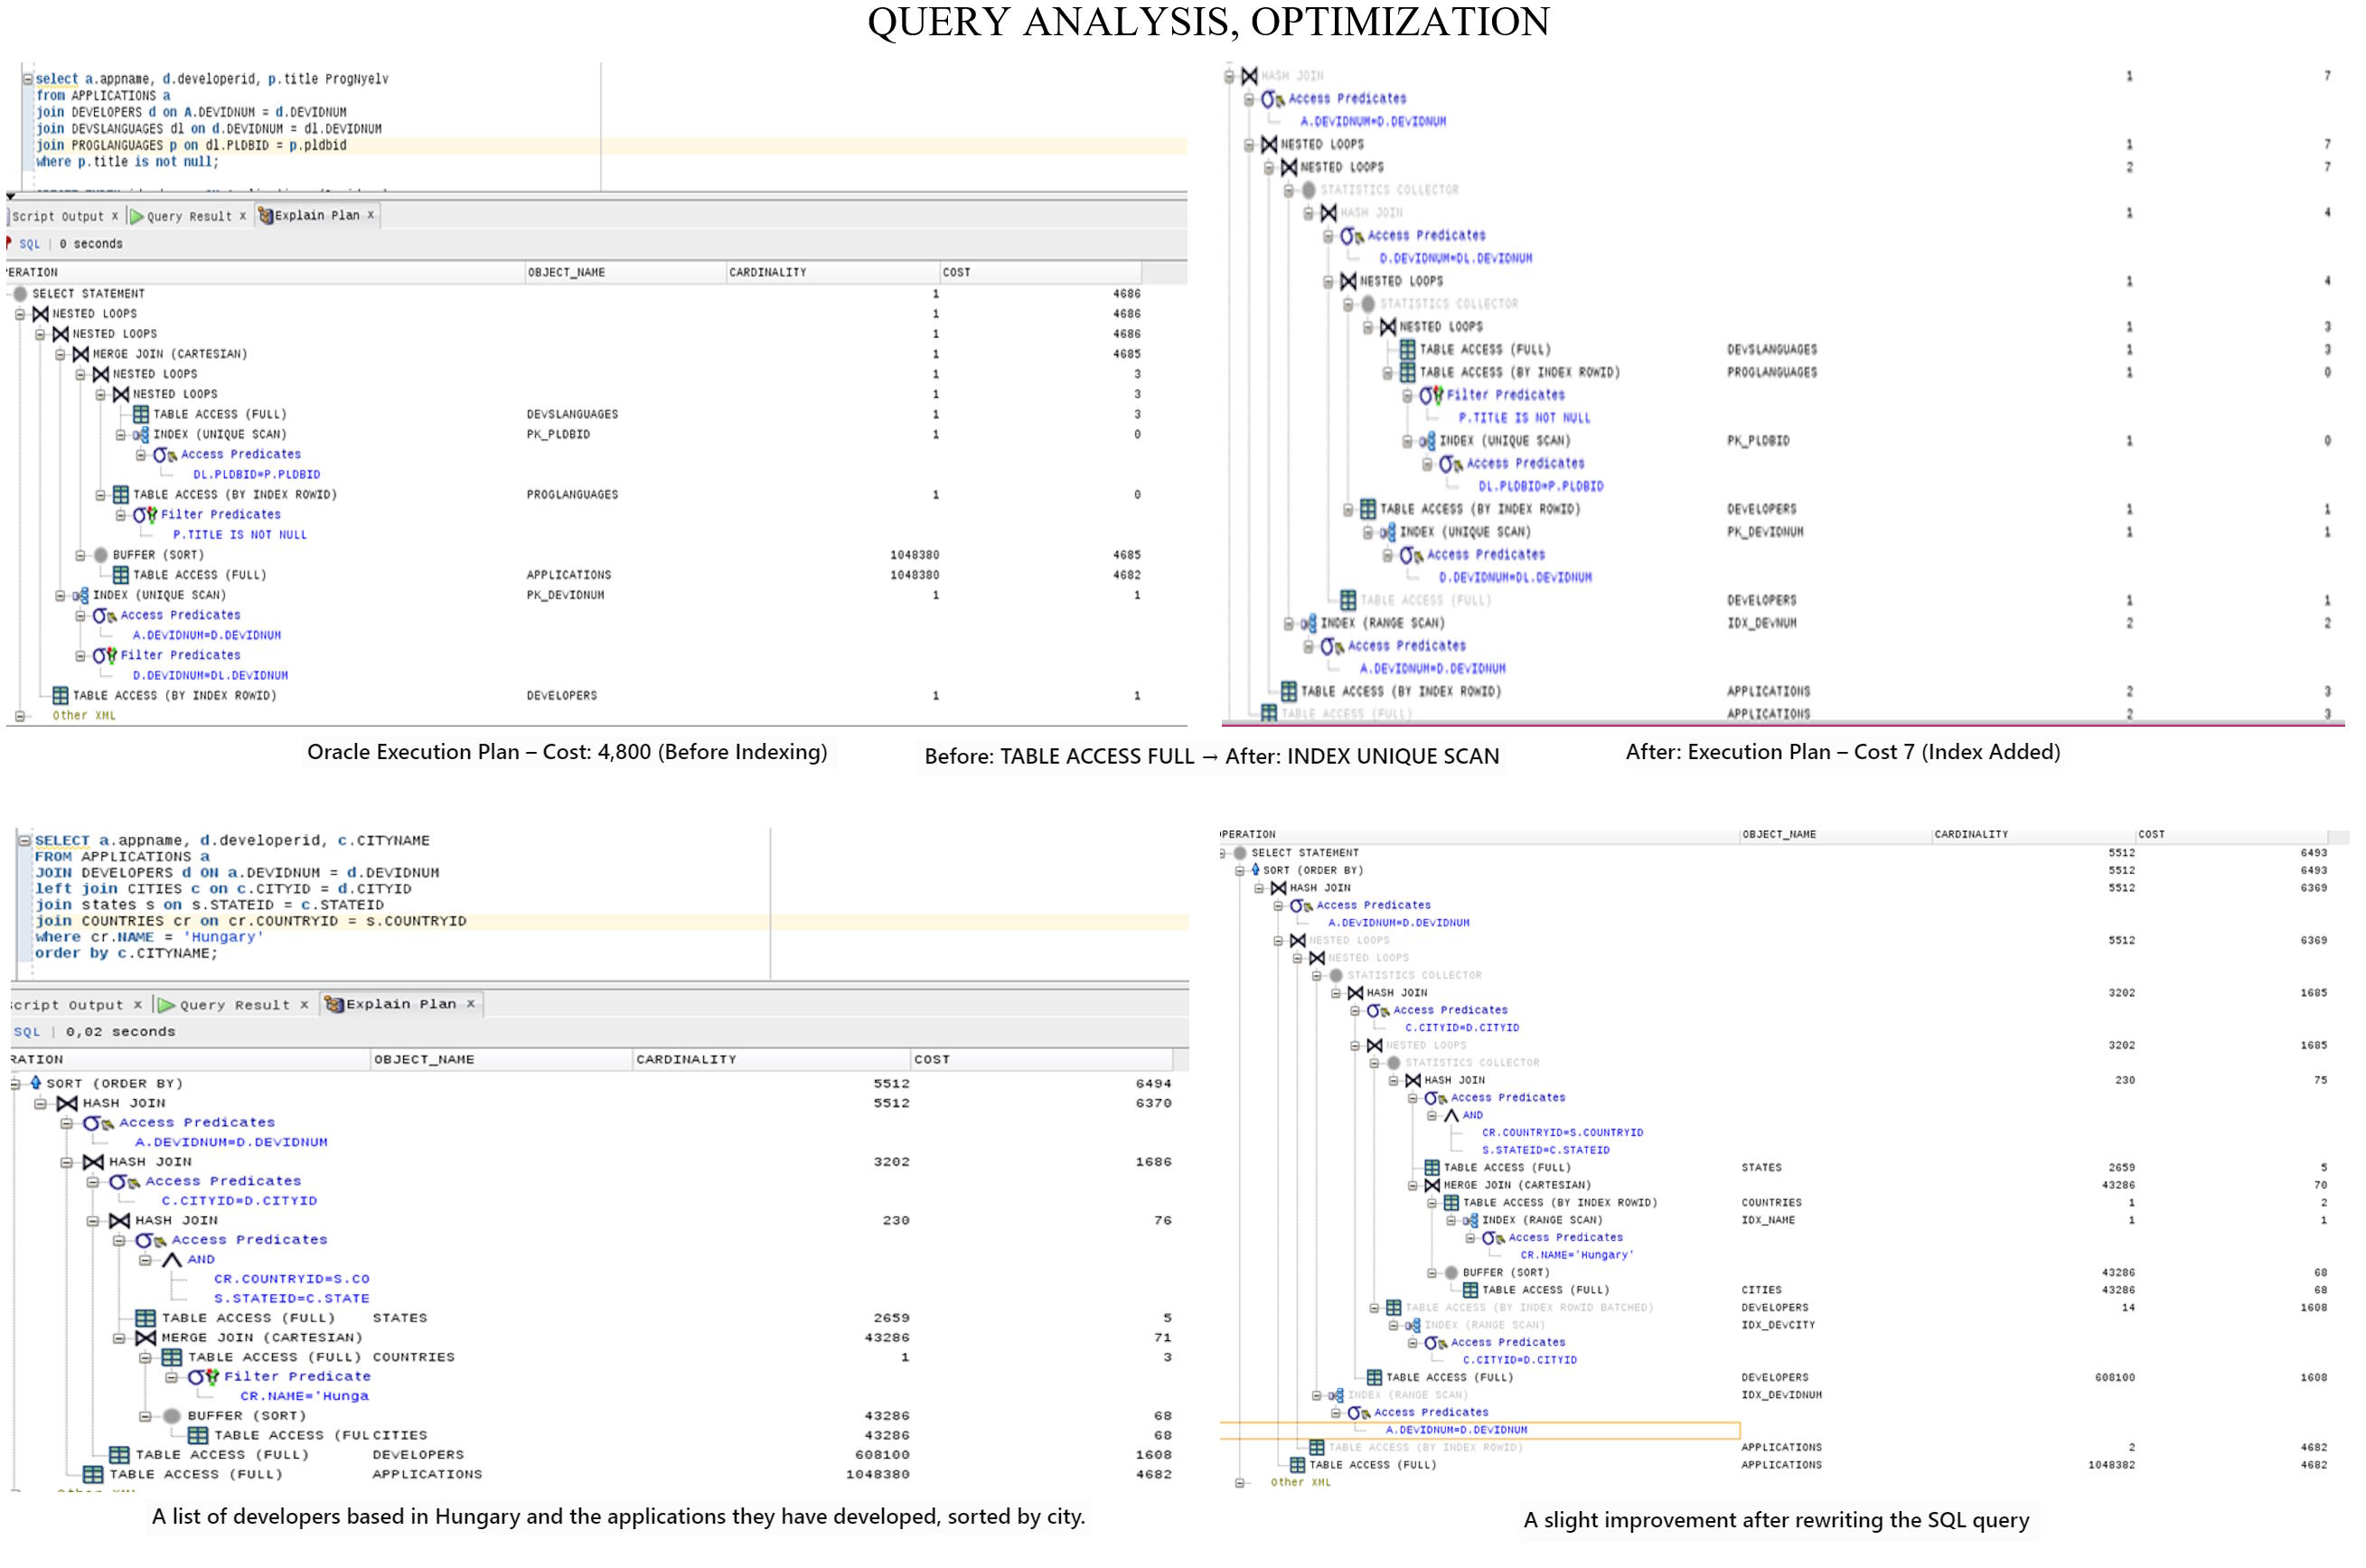
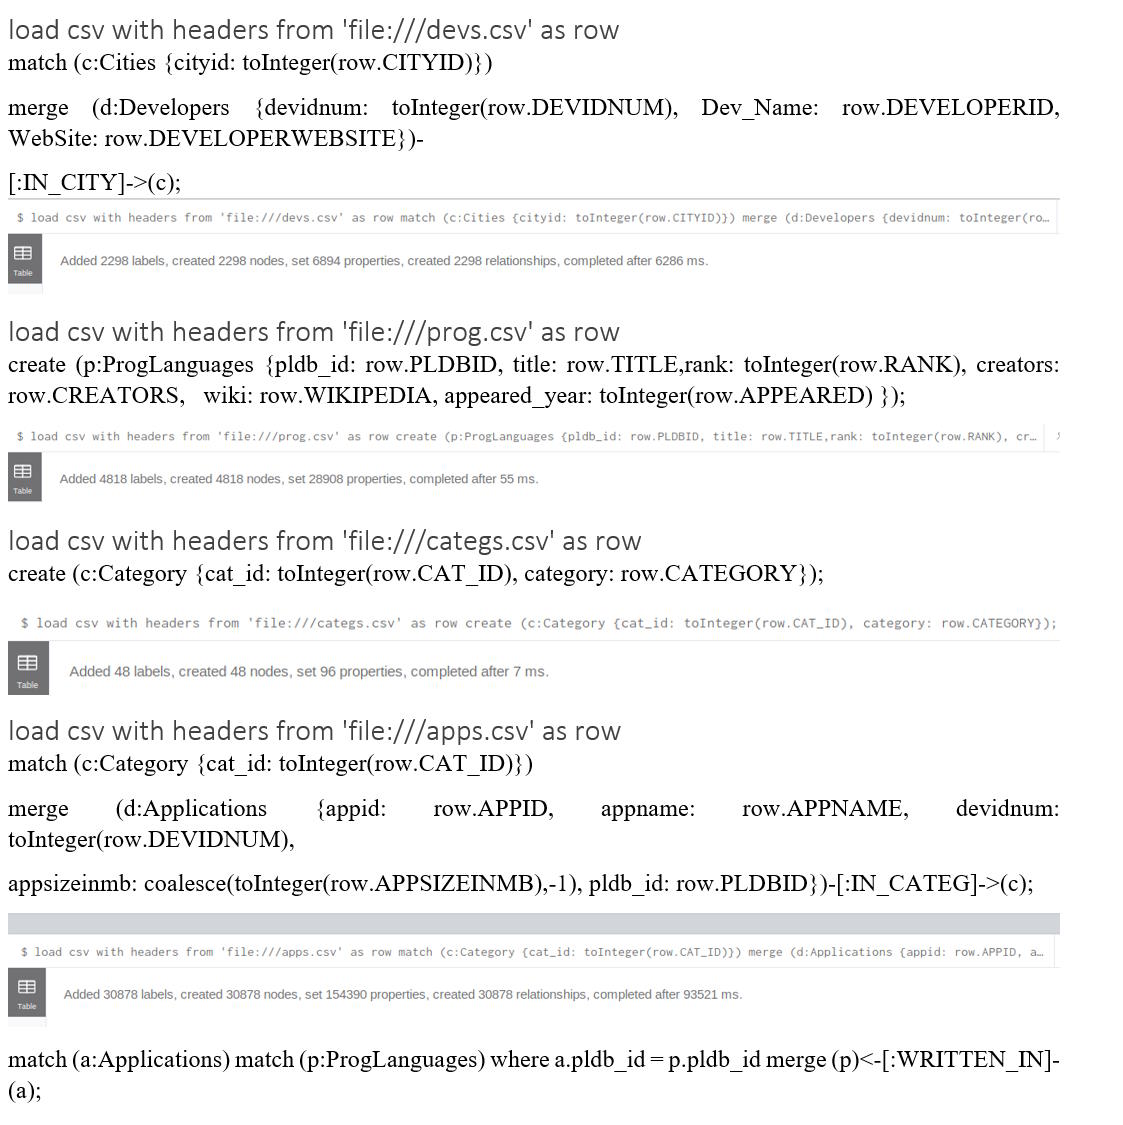
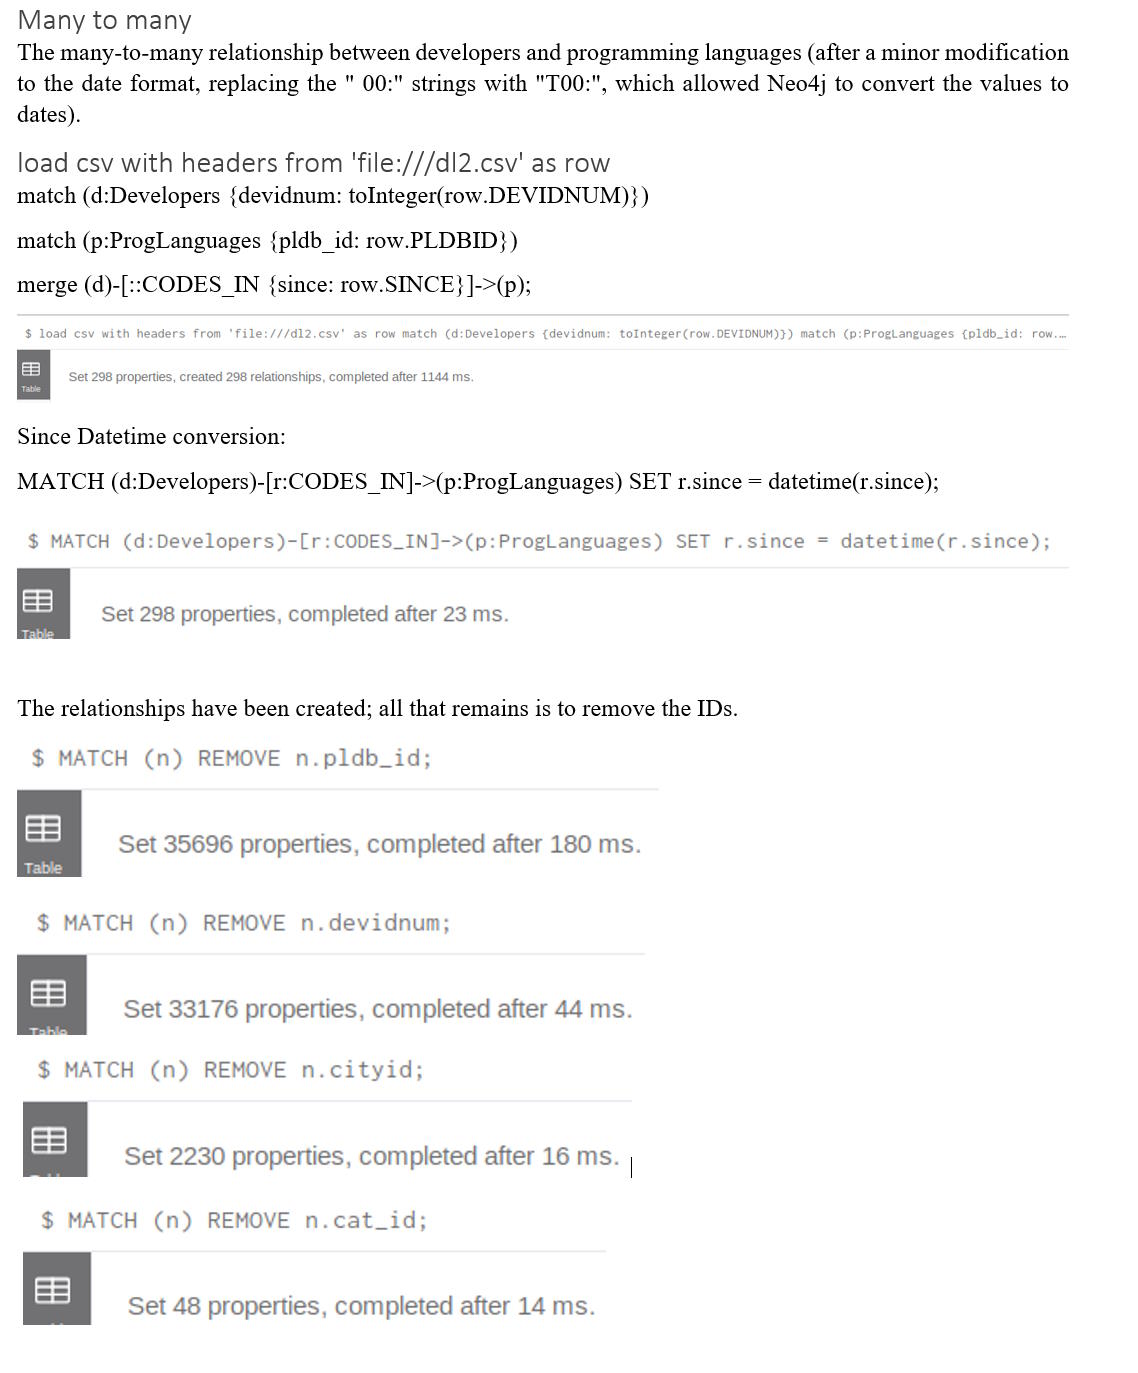
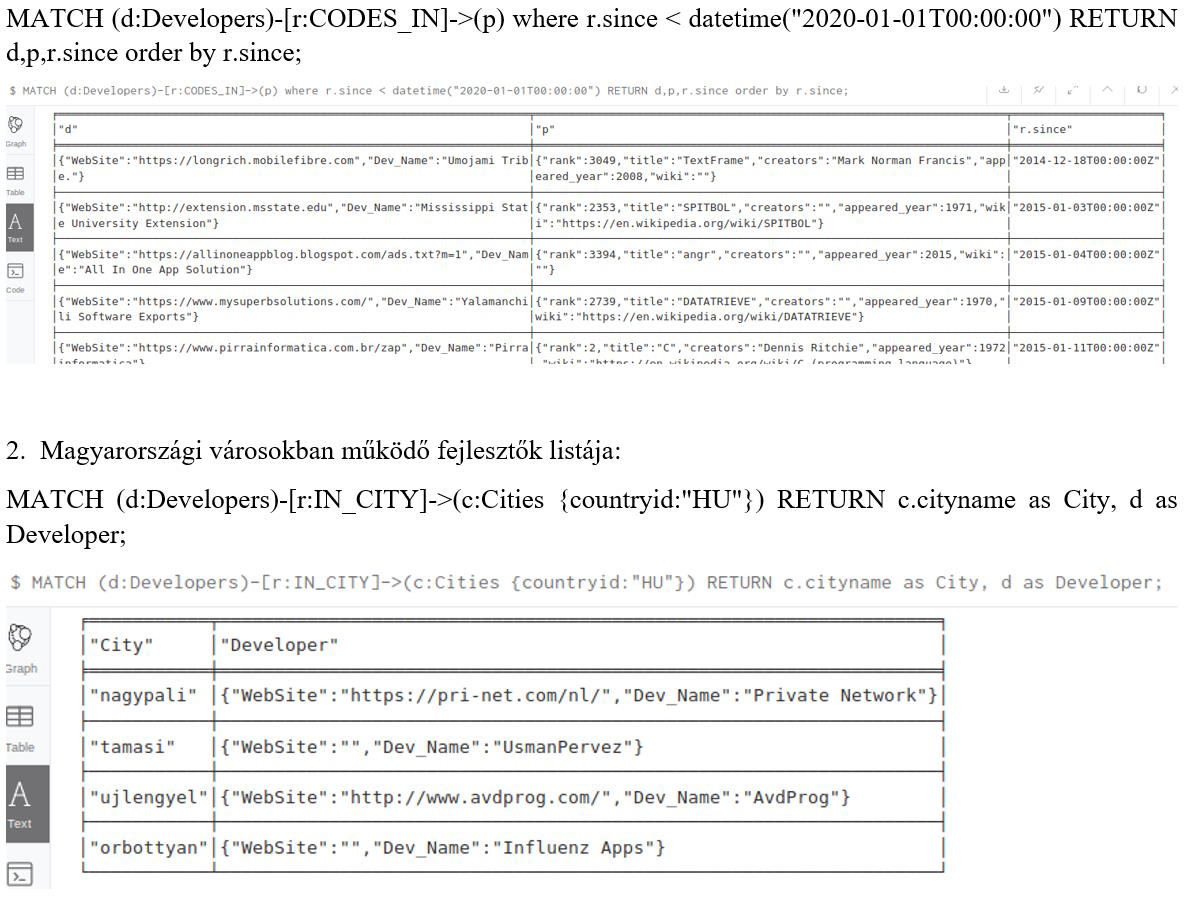
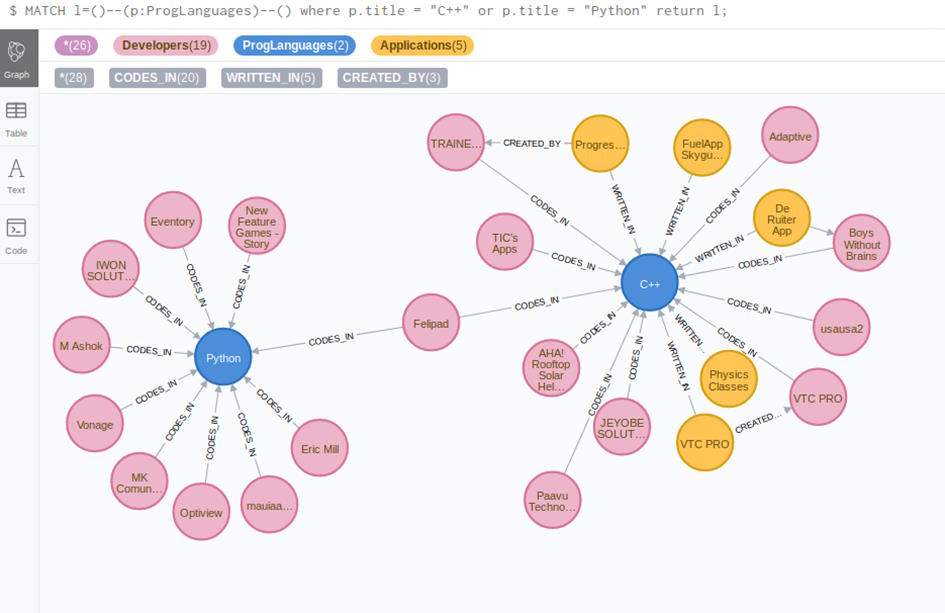
This project is an application registry database, initially built in Oracle SQL and later migrated to Neo4j. The core dataset-containing information about applications, developers, and programming languages-was sourced from Kaggle. Some of the raw CSV and XLS files contained millions of rows. I built a custom data preparation pipeline to handle the raw CSV files. Using custom C# scripts, I cleaned formatting errors, normalized the structures, and merged the datasets into an import-ready format. The initial import process generated the base CREATE SQL statements, which I then manually refined to set up the proper relational schema. Once the Oracle database was running, I wrote and optimized various queries, applying indexing to improve execution times. The domain involved many-to-many (N:M) relationships, so I chose Neo4j for the next phase. I handled the data export-import process to migrate everything from Oracle to Neo4j and built graph visualizations to map out the connections. The entire workflow, from data cleaning to the final graph models, was documented in a 30-page technical report, accompanied by a 20-page appendix containing all the C# and database scripts.